|
|
|
2026.09
One paper introducing a benchmark for conditional optimization was accepted by NeurIPS 2026.
2026.09
The technical report on DianShi-RxnDB, an organic reaction database, was released.
2026.05
One paper on spectral learning was accepted by KDD 2026.
2026.05
One paper on cross-modal person re-identification was accepted by TIP.
2026.02
One paper about video temporal grounding accepted by TIP.
2026.01
One paper about interpretability for visual prompt tuning accepted by ICLR 2026.
2025.05
Joined Shanghai AI Lab as an algorithm engineer. Focus on parsing chemistry-related documents.
2025.03
Graduated from Tongji University with a Master's degree.
2025.01
One paper about 3D object detection accepted by ICLR 2025.
2024.07
Joined MSRA Shanghai as a research intern. Focus on explainibility and knowledge discovery in vision.
2024.02
One paper about prompt learning accepted by TIP.
2024.01
Joined Baidu Inc. at Shanghai as a research intern. Focus on 3D vision.
2023.12
One paper about prompt learning accepted by AAAI 2024.
2022.09
Became a graduate student at Tongji University.
2022.07
One paper about text-based person re-id accepted by PRCV 2022, Oral.
2021.07
Joined VILL Lab, advised by Prof. Cairong Zhao.
2021.05
My first paper about opinion summarization accepted by IJCRS 2021.
|
|
|
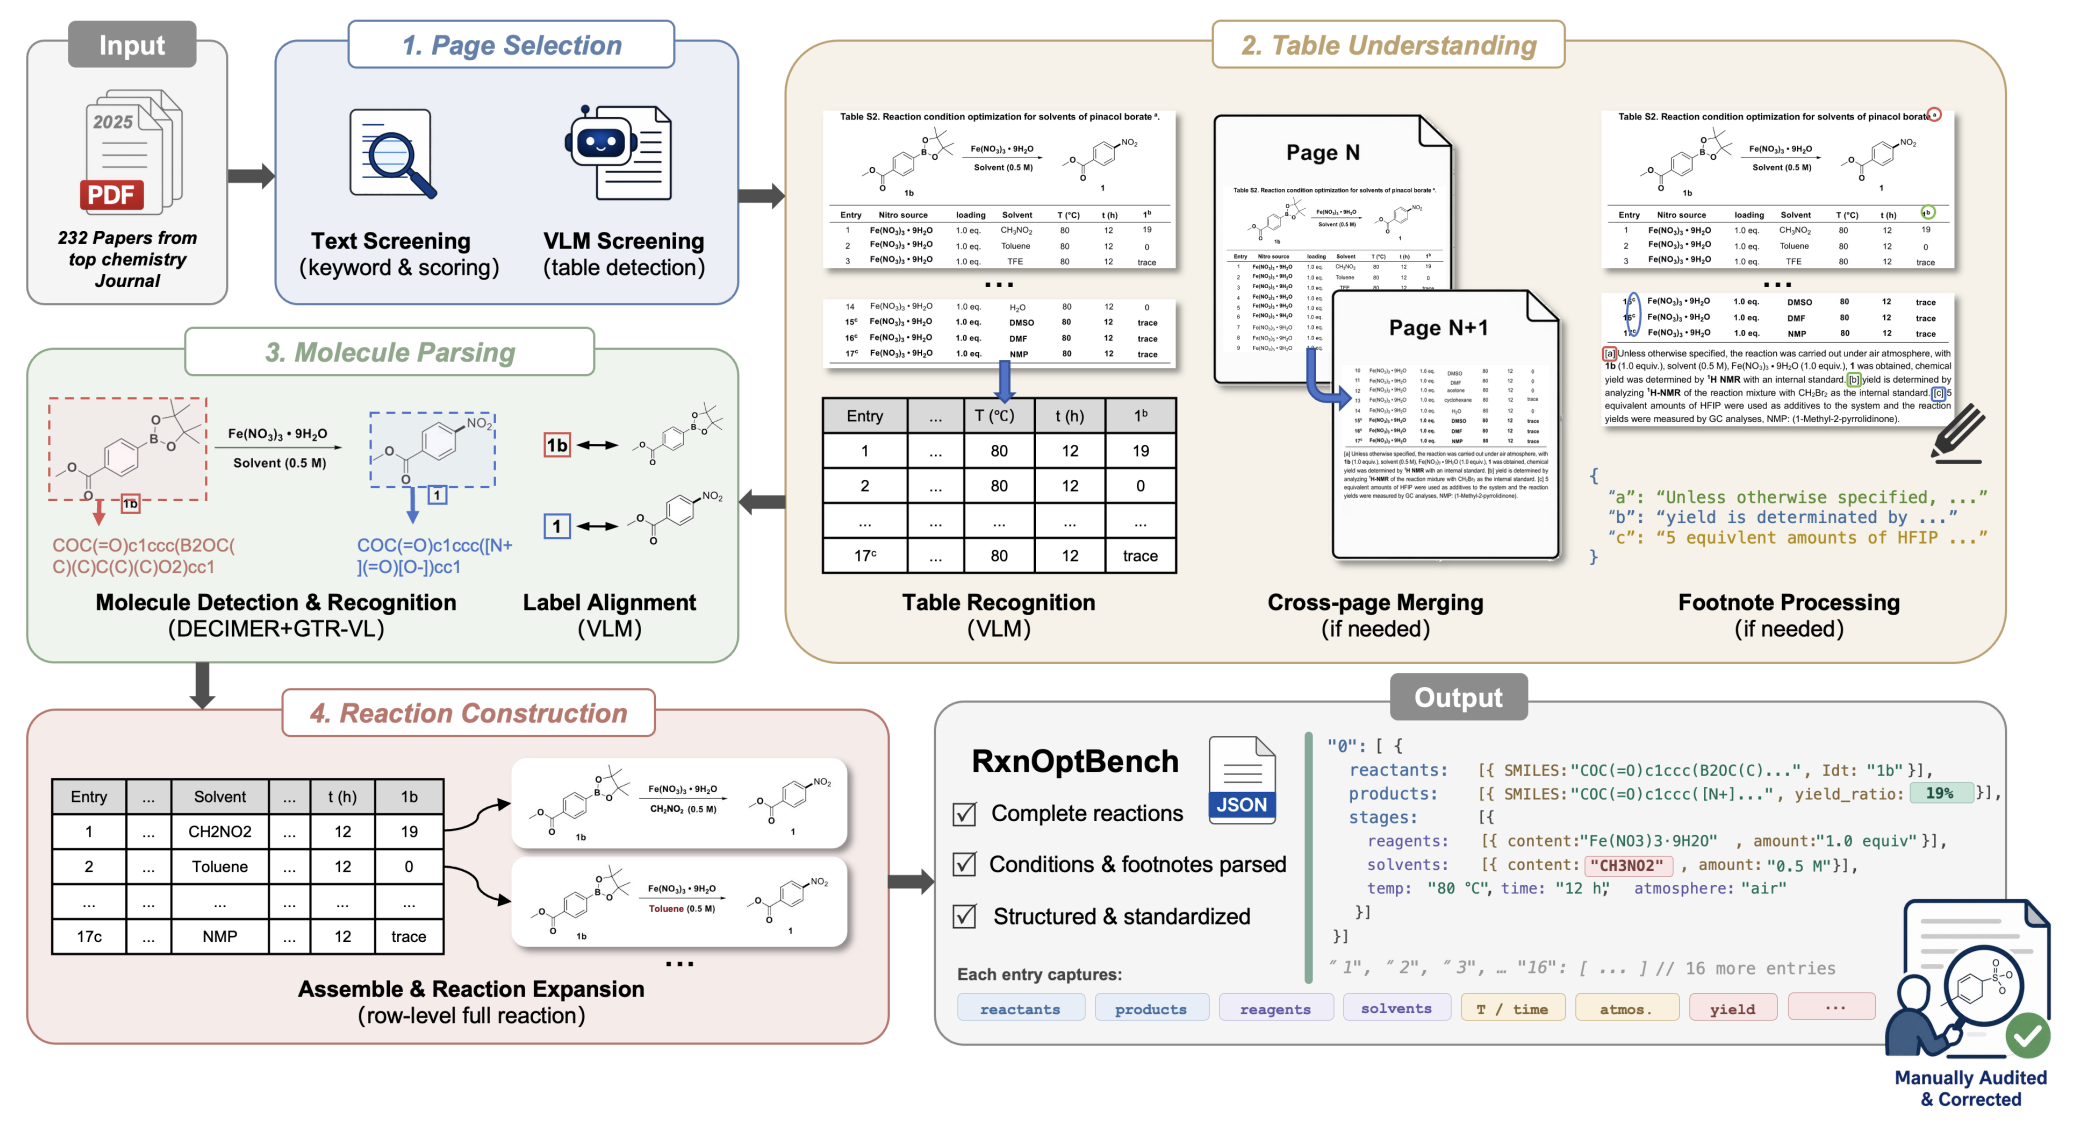 |
Lingli Ge, Yubin Wang, Junyuan Gao, Jiahe Song, Jiaxing Sun, Boyu Zhu, Haote Yang, Jingchao Wang, Lixin Ma, Jiang Wu, Yuqiang Li, Conghui He The 40th Annual Conference on Neural Information Processing Systems, Evaluations and Datasets Track, NeurIPS 2026 (CCF-A) [PDF] RxnOptBench evaluates how well large language models optimize chemical reaction conditions using real experimental data from organic methodology papers. It includes reaction screening options and literature precedents, with scores reflecting yield and stereoselectivity. Evaluations across frontier and chemistry-focused language models show substantial room for improvement in selecting the best conditions. |
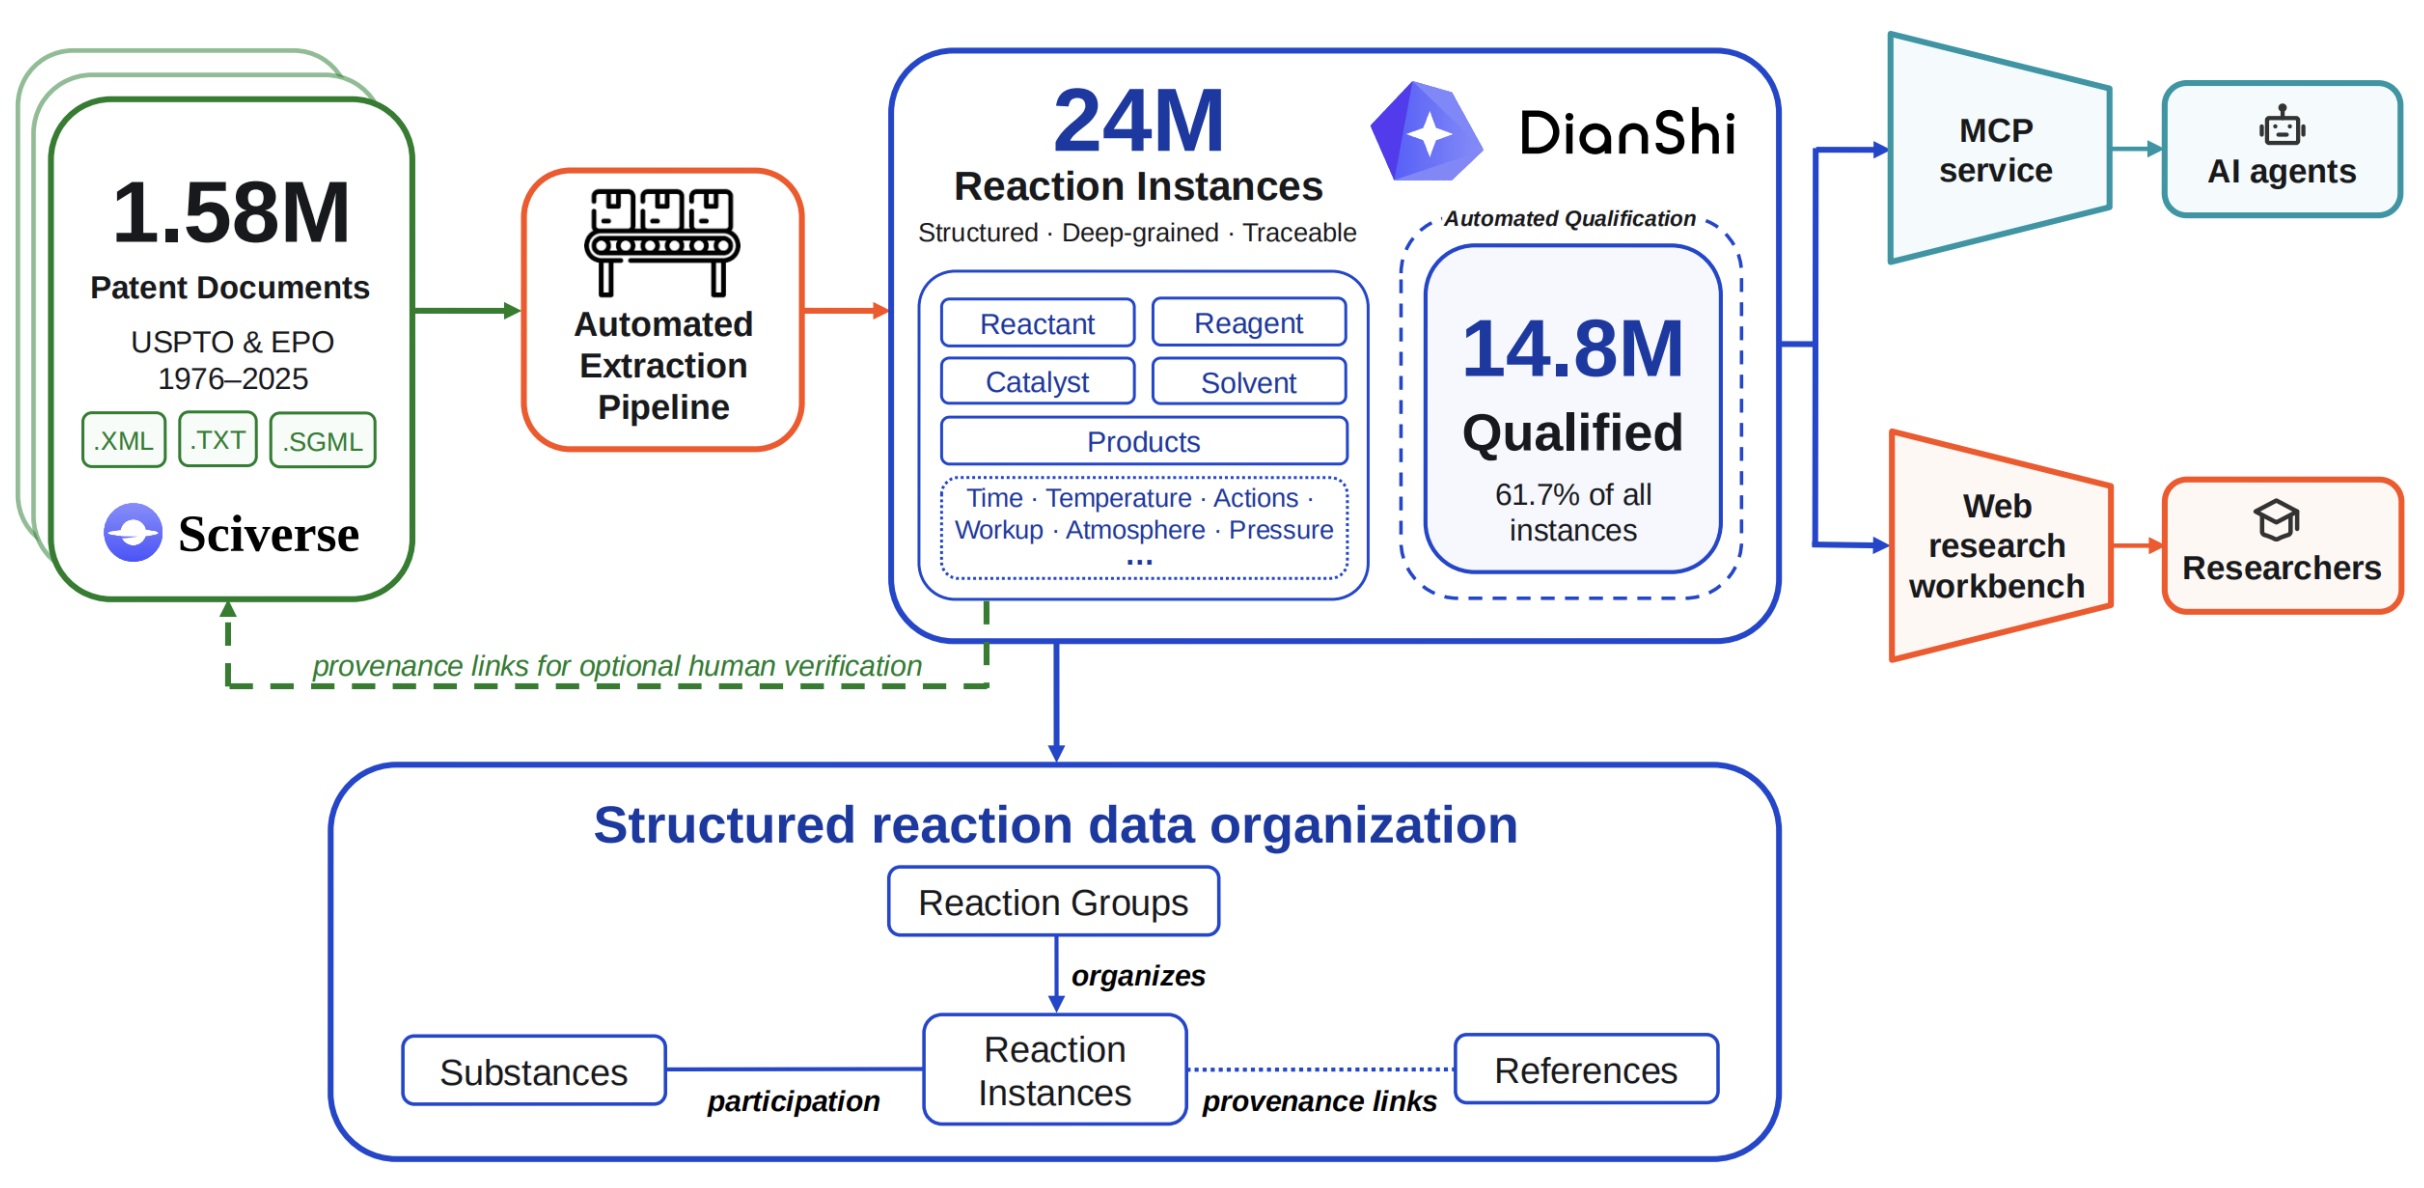 |
Yubin Wang*, Xingjian Wei*, Jiang Wu*, Yinfan Wang, Boyu Zhu, et al. Technical Report, 2026 [PDF] [Database] DianShi-RxnDB is a large-scale organic reaction data platform built through an automated pipeline that extracts and normalizes information from patent text, images, and reaction schemes. It covers patents from the USPTO and EPO published between 1976 and 2025, with approximately 24 million reaction instances. The platform provides a web workbench for researchers and structured retrieval tools for AI agents. |
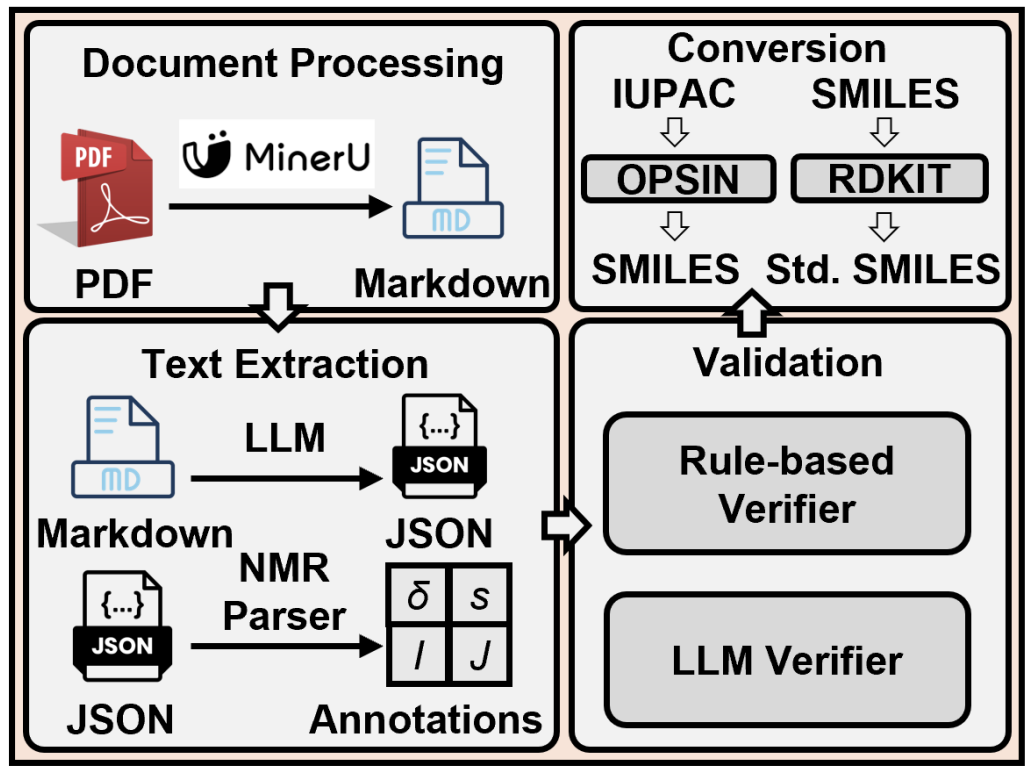 |
Liujia Yang*, Zhuo Yang*, Jiaqing Xie*, Yubin Wang*, Ben Gao, Tianfan Fu, Xingjian Wei, Jiaxing Sun, Jiang Wu, Conghui He, Yuqiang Li, Qinying Gu The 32nd ACM SIGKDD Conference on Knowledge Discovery and Data Mining, AI4Science Track, KDD 2026 (CCF-A) [PDF] NMRTrans uses Set Transformers to elucidate molecular structures from experimental nuclear magnetic resonance spectra. The work introduces NMRSpec, a large corpus of experimental proton and carbon-13 spectra, and represents each spectrum as an unordered set of peaks. On experimental benchmarks, it improves Top-10 accuracy over the strongest baseline from 43.33% to 61.15%. |
|
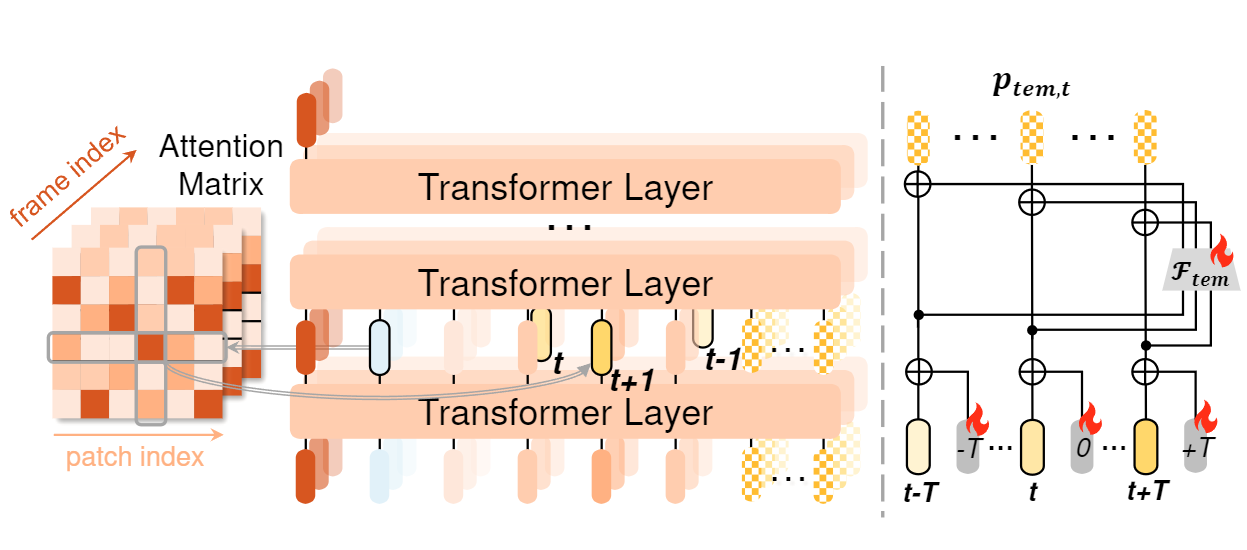
Yubin Wang, Xinyang Jiang, De Cheng, Dongsheng Li, Cairong Zhao IEEE Transactions on Image Processing, TIP (CCF-A, SCI) [PDF] ActPrompt improves video temporal grounding by adapting pre-trained vision-language features to video domains and injecting action cues into the image encoder. It combines efficient in-domain feature adaptation with temporal prompting to distinguish actions from static visual content. Experiments show that the framework improves multiple existing grounding methods.
|
|
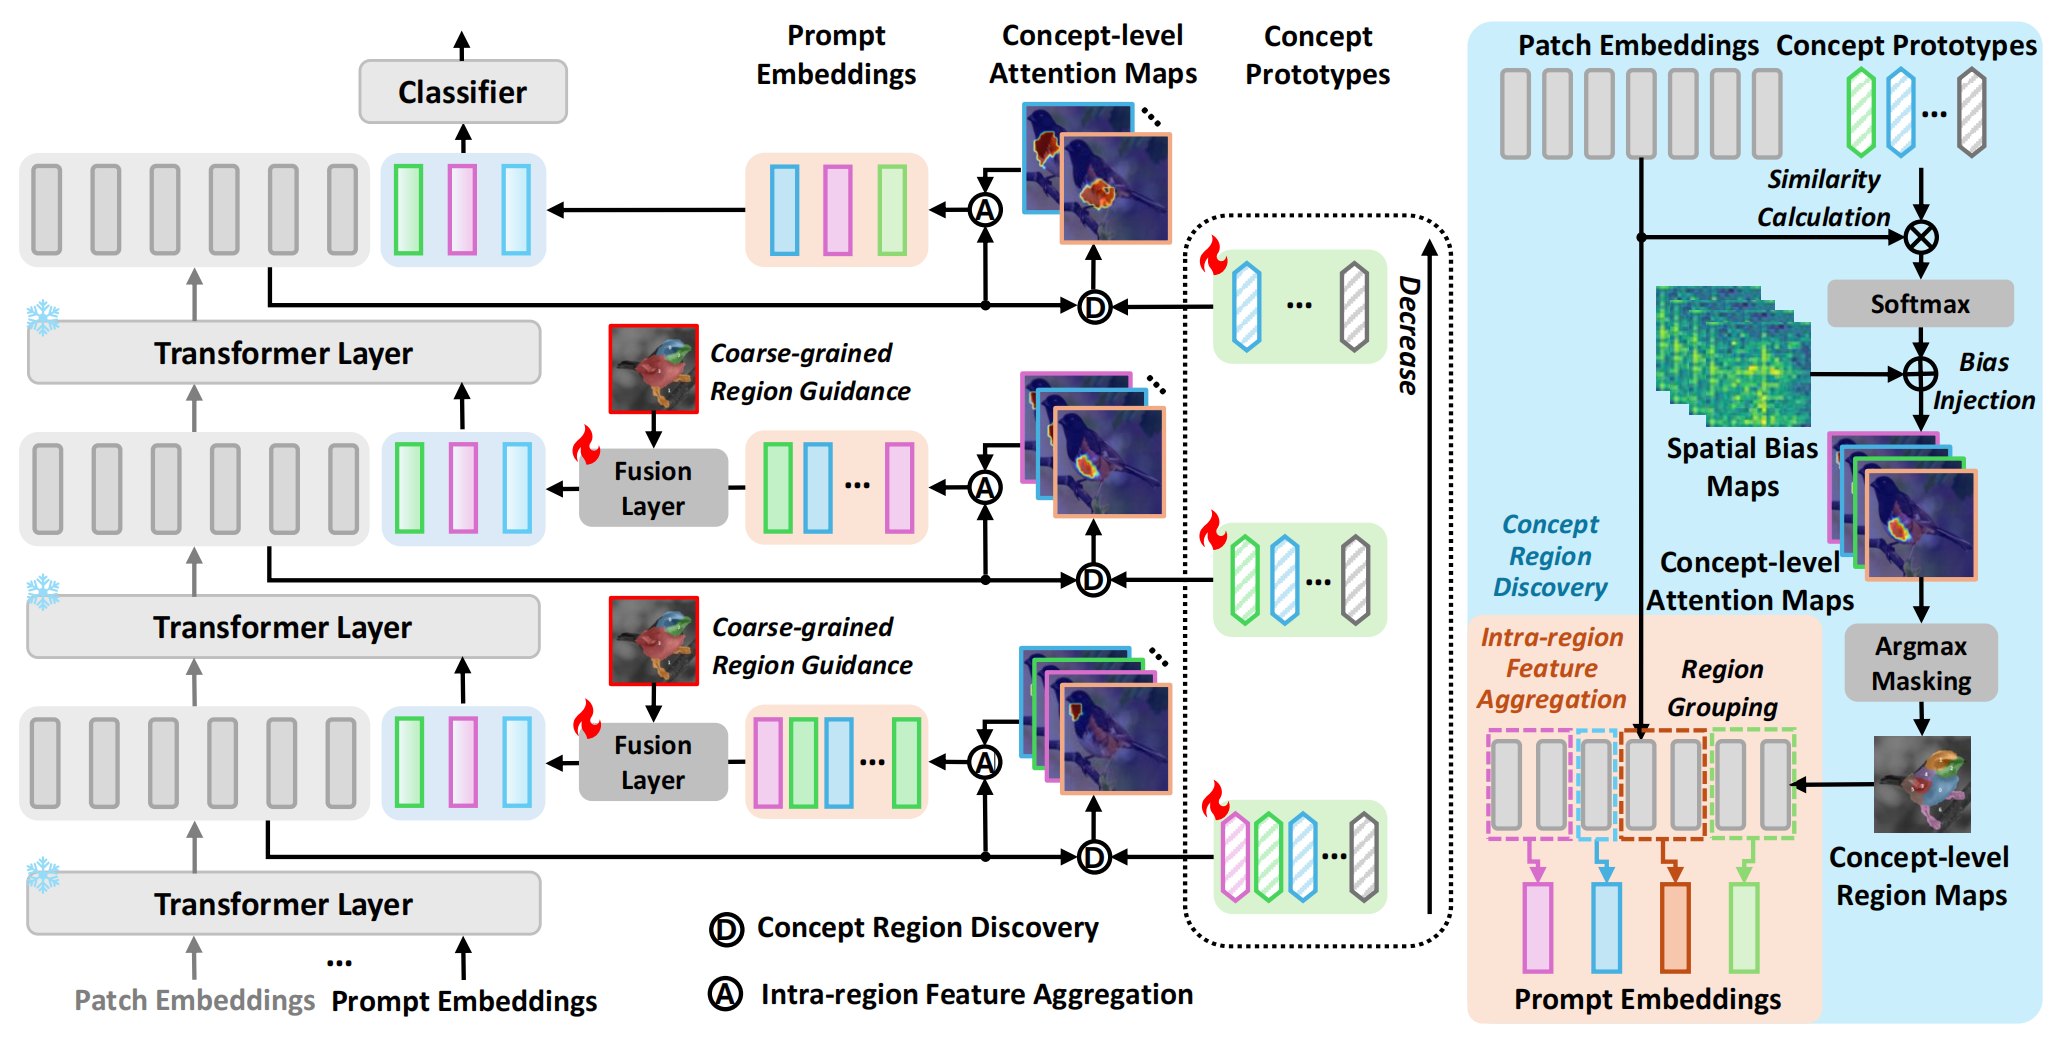
Yubin Wang, Xinyang Jiang, De Cheng, Xiangqian Zhao, Zilong Wang, Dongsheng Li, Cairong Zhao The 14th International Conference on Learning Representations, ICLR 2026 (CCF-A) [PDF] Interpretable Visual Prompt Tuning (IVPT) links visual prompts to human-understandable concept prototypes derived from image regions. It aggregates these regional features across model layers to explain prompts at different depths and semantic levels. Experiments on fine-grained classification benchmarks show strong performance and improved interpretability.
|
|
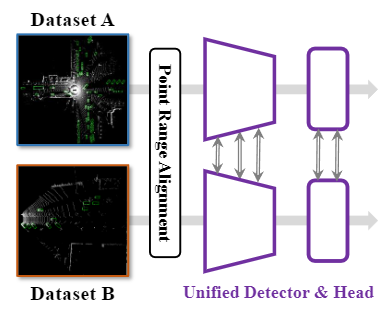
Yubin Wang*, Zhikang Zou*, Xiaoqing Ye, Xiao Tan, Errui Ding, Cairong Zhao The 13th International Conference on Learning Representations, ICLR 2025 (CCF-A) [PDF] Uni²Det unifies multi-dataset 3D object detection with prompt modules that account for differences in data distributions and object taxonomies. Its multi-stage prompts integrate with existing detectors and support training across KITTI, Waymo, and nuScenes. Experiments show improved multi-dataset detection and generalization to unseen datasets.
|

|
Cairong Zhao*, Yubin Wang*, Xinyang Jiang, Yifei Shen, Kaitao Song, Dongsheng Li, Duoqian Miao IEEE Transactions on Image Processing, TIP (CCF-A, SCI) [PDF] [Code] MetaPrompt learns domain-invariant prompts for vision-language models in few-shot settings. It combines visual and textual prompt tuning with asymmetric contrastive learning and domain-split updates to improve cross-class and cross-domain transfer. Results across base-to-new and domain-generalization benchmarks show stronger generalization than previous prompt-learning methods.
|

|
Yubin Wang, Xinyang Jiang, De Cheng, Dongsheng Li, Cairong Zhao The 38th Annual AAAI Conference on Artificial Intelligence, AAAI 2024 (CCF-A) [PDF] [Code] Hierarchical Prompt Tuning (HPT) uses language-model-generated graphs of category descriptions to bring structured knowledge into vision-language prompt learning. Relationship-guided attention captures links between entities and attributes, while hierarchical prompts combine local and global semantics. Experiments show improved effectiveness and generalization over previous approaches.
|
|
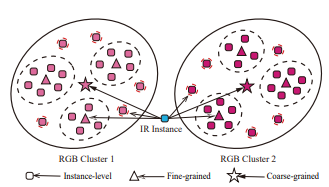
Haonan Shi, Yubin Wang, De Cheng, Lingfeng He, Nannan Wang, Xinbo Gao IEEE Transactions on Image Processing, TIP (CCF-A, SCI) [PDF] Hierarchical Identity Learning (HIL) addresses unsupervised visible-infrared person re-identification by representing each identity cluster with multiple fine-grained centers. Multi-center contrastive learning improves representations within and across modalities, while bidirectional selection builds reliable cross-modal matches. Experiments on SYSU-MM01 and RegDB show improved retrieval performance.
|
|
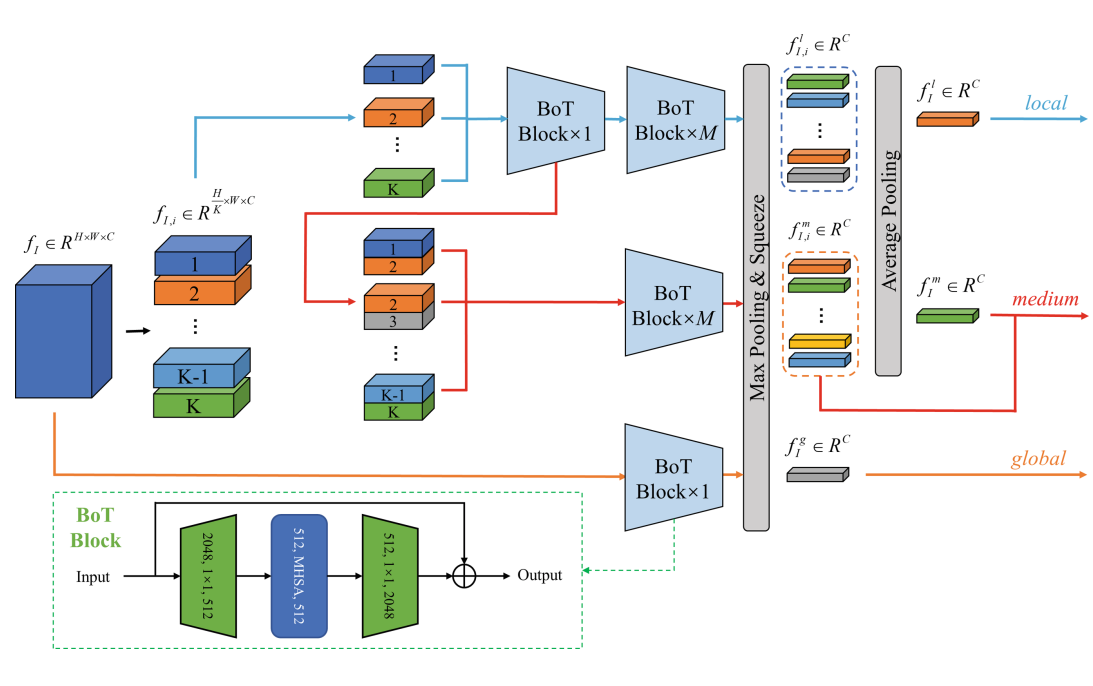
Yubin Wang, Ding Qi, Cairong Zhao Chinese Conference on Pattern Recognition and Computer Vision, PRCV 2022 (CCF-C, Oral) [PDF] Part-Based Multi-Scale Attention Network (PMAN) retrieves people from text by combining visual features at multiple scales with textual features. It uses a Bottleneck Transformer for representation learning and a cross-modal matching strategy to align descriptions with image regions. Experiments on CUHK-PEDES show improved person-search performance.
|

|
Han Jiang*, Yubin Wang*, Songhao Lv, Zhihua Wei Rough Sets: International Joint Conference, IJCRS 2021 [PDF] This system summarizes opinions in social media discussions using BERT-based subjectivity analysis and data-mining methods. It includes an evaluation module with hierarchical metrics to assess the resulting summaries. Experiments and ablation studies show that the pipeline produces concise summaries of the main opinions.
|
|
|
|
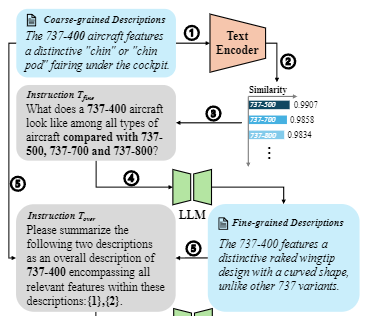
Yubin Wang, Xinyang Jiang, De Cheng, Wenli Sun, Dongsheng Li, Cairong Zhao Artificial Intelligence, AI (CCF-A, SCI) [PDF] HPT++ extends hierarchical prompt tuning for vision-language models with multi-granularity knowledge generation and improved graph-based structure modeling. It strengthens relationship-aware attention and adds consistency constraints to the hierarchical text encoder. Experiments across base-to-novel, cross-dataset, and domain-generalization settings show consistent gains over previous methods.
|
|
I'm Wang Yubin. My hometown is Fuzhou, Fujian Province, China. I hope to meet more like-minded friends through this platform, so we can exchange ideas and grow together! |